To generate realistic insurance claims test data, start with one document-intake workflow, define the fields and outcomes it must support, and create fictional documents with controlled variations. Keep business conditions separate from image-quality defects, record the expected result for every sample, and review the generated documents before using them to evaluate a system.
Realistic does not simply mean a document looks convincing. A useful test document represents a specific condition your intake pipeline must handle: a readable claim form, a missing identifier, an unexpected attachment, or a scan whose key field cannot be read reliably.
This guide focuses on testing document intake and extraction. It does not define coverage, determine claim validity, or replace claims adjudication.
Start with one intake workflow, not “insurance data”
A health-insurance form, a vehicle repair estimate, and a property-loss report are different testing problems. Combining them before defining the workflow makes it harder to tell whether a failure comes from classification, extraction, document quality, or an unsupported format.
Write a short test specification before generating files:
- Input: Which document type, version, language, and file formats does this workflow accept?
- Output: Which fields, tables, document labels, or exception signals should it produce?
- Boundary: What does the pipeline extract, and what must it leave to a downstream system or reviewer?
- Failure behavior: What should happen when required evidence is missing or unreadable?
For example, an illustrative claims-intake test might require a claim identifier, service date, and billed amount from an accepted form. It might also require the pipeline to distinguish an unsupported attachment from an unreadable accepted form. These are proposed test requirements, not universal insurance rules.
Have the workflow owner approve this specification. An engineering team should not invent business acceptance rules from the appearance of a form.
Separate business conditions from document conditions
There are two independent reasons a document may be difficult to process.
Business conditions concern the information: a required field is blank, an identifier has an invalid format, or two amounts disagree under a rule your team has explicitly defined.
Document conditions concern the representation: blur, rotation, poor lighting, cropping, compression, or a low-quality fax.
A clean scan can contain incomplete information. A blurred scan can depict an otherwise complete form. Calling both “negative samples” hides the difference.
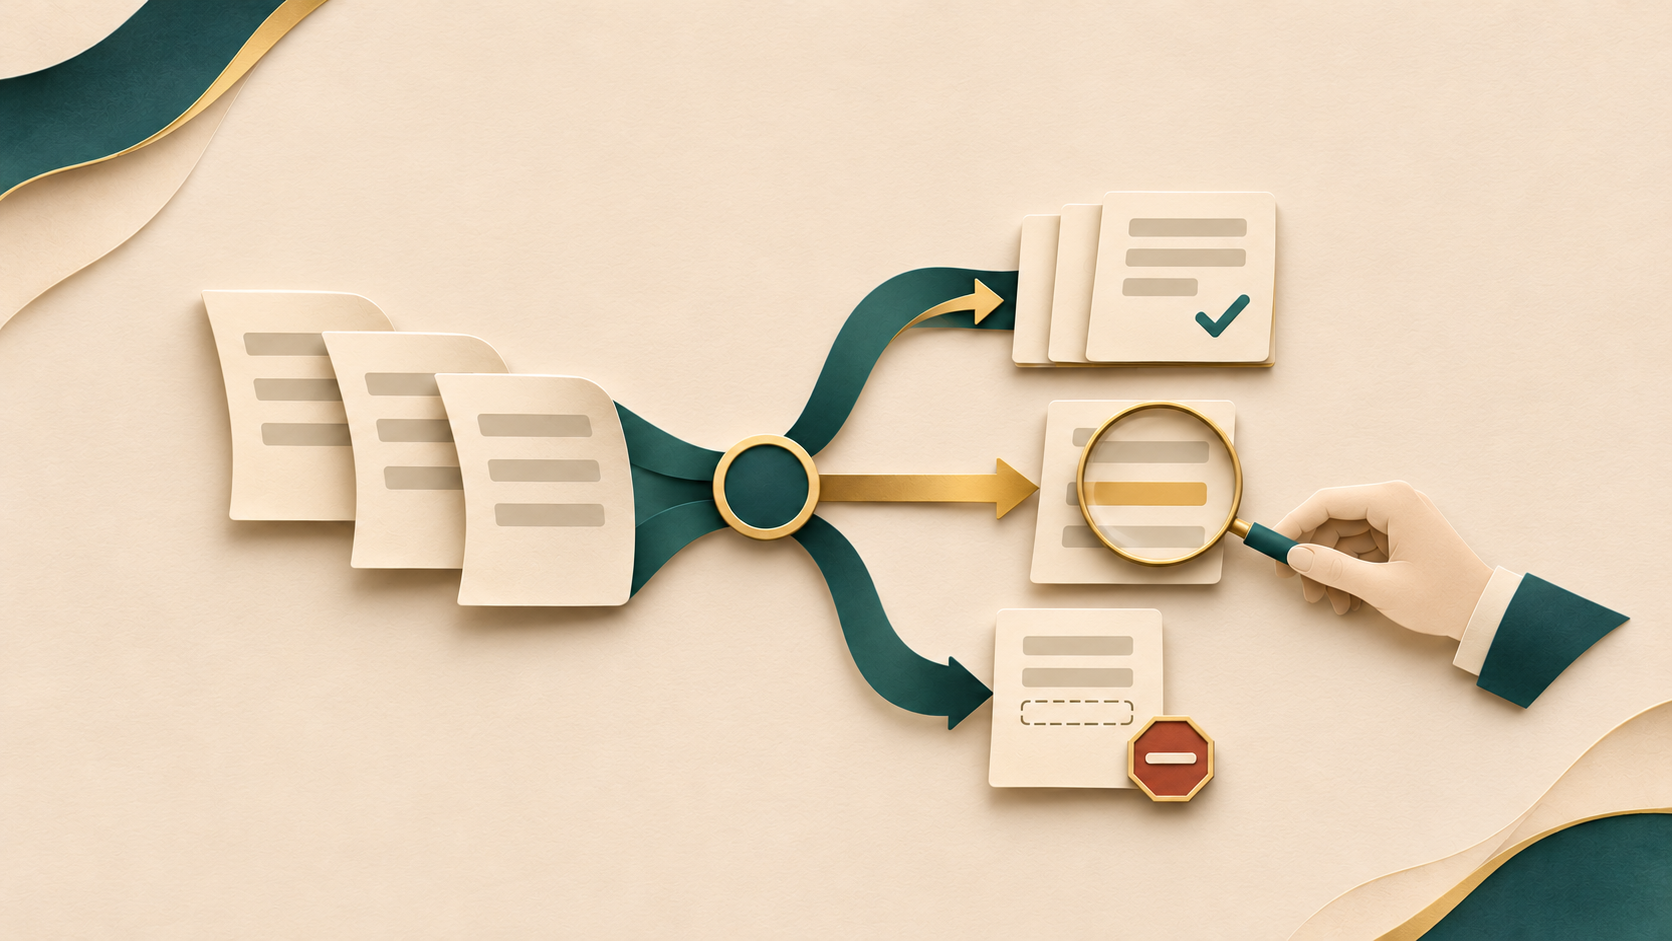
Use a small scenario matrix such as this illustrative starting set:
- Baseline: required fields present in a clean document. Extract the specified fields.
- Missing identifier: identifier intentionally blank in a clean document. Report missing information.
- Difficult capture: required fields present with controlled blur. Extract only supported values and flag uncertainty where needed.
- Cropped identifier: identifier exists in the source but is cut off in the received image. Report unavailable evidence, not a guessed value.
- Unsupported attachment: a different document type, even if clean. Route according to the documented unsupported-input policy.
Do not automatically label a blurred file as a failure case. Some degradation remains readable. Review the rendered sample and assign the expected behavior to what it actually shows.
Generate a baseline before adding variations
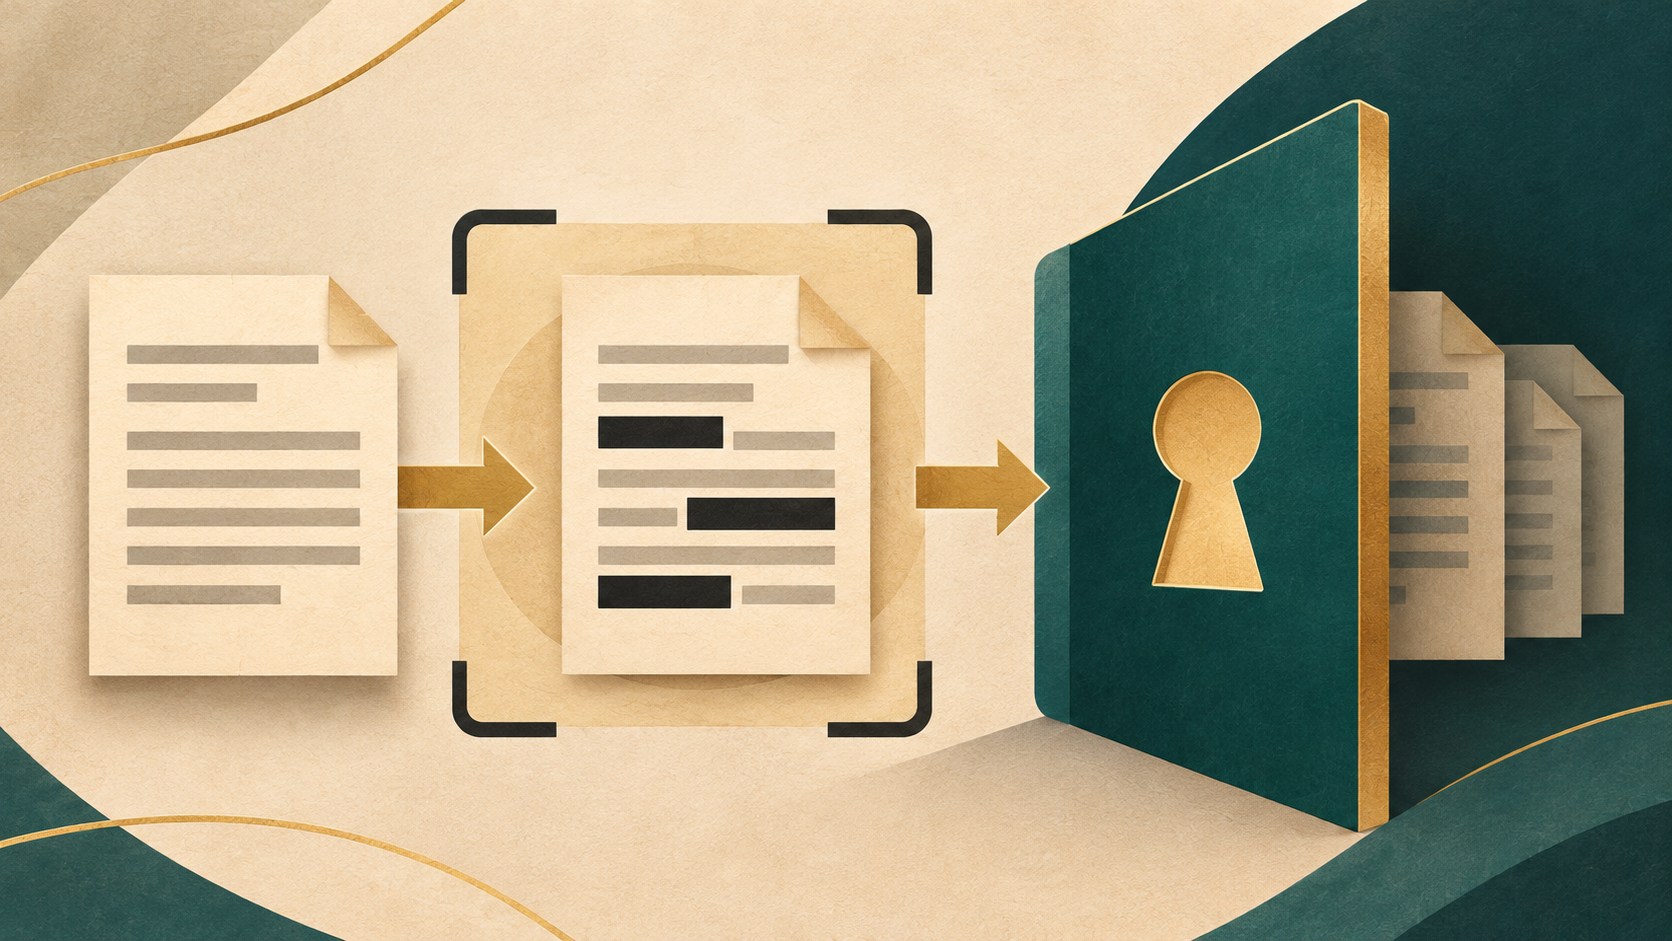
Begin with a blank template or a reviewed, sanitized seed that you have permission to use. Define fictional values and the relationships that matter to the test, then render a clean document.
Inspect that baseline before generating a larger batch. Check that values appear in the correct fields, text does not overflow, labels remain readable, and the document is clearly marked for testing where appropriate. A convincing layout with misplaced values is a generation defect, not a useful challenge for your extraction pipeline.
GritRender supports synthetic document generation with defined fields, rules, relationships, and controlled variations. The appropriate configuration still depends on your document type and test specification; a product capability is not evidence that a particular insurance dataset has already been validated.
If you start from real documents, replacing names alone is not enough to establish that they are safe to reuse. Review identifiers, free text, images, annotations, and other content that could expose sensitive information. GritRedact supports sensitive-content redaction workflows, but source permissions and review remain separate responsibilities.
Change one condition at a time first
Create a clean baseline and a small number of controlled variants before combining defects. This makes failures easier to explain.
A useful sequence is:
- Generate and inspect the clean form.
- Add one visual variation, such as rotation or blur.
- Confirm that the intended change occurred and that unrelated content stayed stable.
- Record whether the target fields remain readable.
- Add combined conditions only after the individual cases are understood.
Image quality and layout are substantive test variables. For example, Amazon Textract’s documented best practices discuss image quality, upright text, and difficulties with irregular tables. Those recommendations support testing capture conditions deliberately; they do not establish universal pass thresholds for every extraction engine.
Eventually, include variation in document layouts and underlying content as well as capture quality. Hundreds of near-identical scans can help diagnose one defect while providing little evidence about generalization to unfamiliar forms.
Keep expected answers outside the document
A PDF is an input artifact, not a complete evaluation package. Maintain a separate manifest describing why each file exists and what the system should do with it.
For each sample, record:
- A stable sample ID and generation version.
- Document type and scenario ID.
- The baseline it was derived from, if applicable.
- The intentional information change or visual transformation.
- Expected field values where the visible evidence supports them.
- Expected missing, unreadable, or unsupported states.
- Reviewer status and any limitations.
Keep the original fictional source value separate from the expected extraction answer. If cropping removes an identifier, the generator may still know the identifier. The extraction system should not be rewarded for returning information absent from its input.
Agree on the representation of these states before testing. A blank string, a missing field, and an explicit unreadable flag are not automatically interchangeable. The extraction-contract guide explains how to make those distinctions explicit.
What can you do with a small downloadable sample pack?
A sample pack is useful for checking your ingestion path and inspecting the kinds of document conditions you want to test. It is not automatically a statistically representative benchmark.
At the time of this review, the insurance ZIP linked from the GritWorks dataset library contained ten PDFs: five labeled positive and five labeled negative. The filenames identify CMS-1500 claim, financial-assistance, and physician-consent examples, with variations including blur, poor lighting, skew, and fax quality. It did not include a separate JSON answer file or evaluation script.
Use those files as starting inputs to inspect, not as a complete claims workflow or evidence of production accuracy. Before scoring a pipeline, confirm the actual document content, define the relevant fields, and create reviewed expected outcomes. A document with “positive” in its filename does not establish that every field meets your own business rules.
For a more systematic field-level evaluation approach, see How to Test OCR Accuracy on Scanned Documents.
Expand coverage only after the small set works
Before increasing volume, ask whether every sample has an explained purpose. Remove accidental duplicates, review generation errors, and ensure that failures can be traced back to a defined scenario.
Keep a separate evaluation set that is not repeatedly used to tune the pipeline. Where layout generalization matters, avoid splitting only cosmetic variants of the same baseline across development and evaluation sets. Decide with your workflow owner which document families and conditions require independent coverage.
Then expand deliberately: additional accepted layouts, longer tables, optional fields, multiple pages, and realistic combinations of capture conditions. Measure performance by scenario rather than allowing an aggregate result to conceal a weak input category.
The immediate goal is not the largest possible dataset. It is a dataset whose inputs, expected outcomes, and limitations your team can explain.
Plan your insurance test dataset
Bring three things to the dataset discussion: the document types you accept, the fields and exception states you need, and the conditions that currently cause trouble. Add expected volume, deployment constraints, and source-data restrictions before deciding how to generate the larger set.
Explore the sample dataset library, or talk to GritWorks about a scenario-led insurance document test set. Start with requirements, not sensitive customer records, so the team can establish the appropriate data-handling process first.