THE GRITWORKS BLOG
Working notes on putting unstructured data to work.
Perspectives on protecting sensitive content, extracting document data, generating realistic examples and building enterprise workflows.
Testing KYC Documents: Extraction, Exceptions and Verification
Use sample identity and onboarding documents to test your document workflow while keeping extraction results separate from identity-verification claims.
How to Test Extraction from Diagnostics Documents
Evaluate lab reports, requisitions and supporting forms with explicit reference fields, paired document conditions and clear limits on what results mean.
How to Generate Realistic Insurance Claims Test Data
Build insurance claims test data around defined intake scenarios, controlled document variations, and explicit expected outcomes. Start small, verify the samples, then expand coverage.
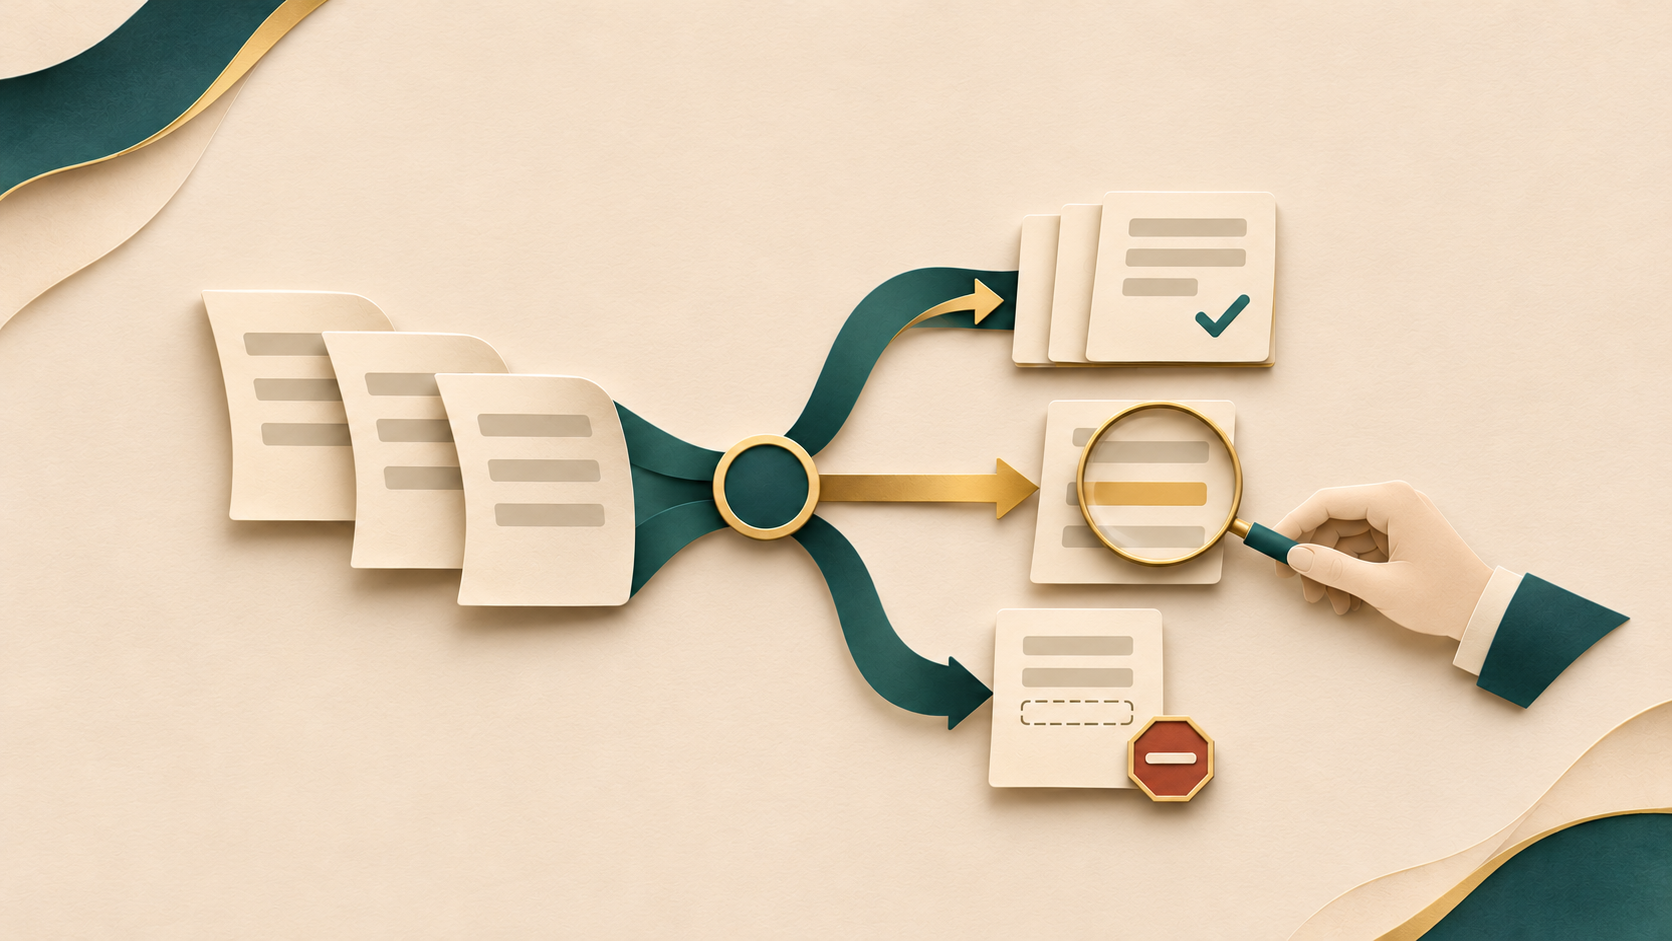
Document Extraction Review Queues: Decide What Needs a Human
Route document extraction results using field importance, validation, source evidence and confidence. Give each exception a clear owner and resolution path.
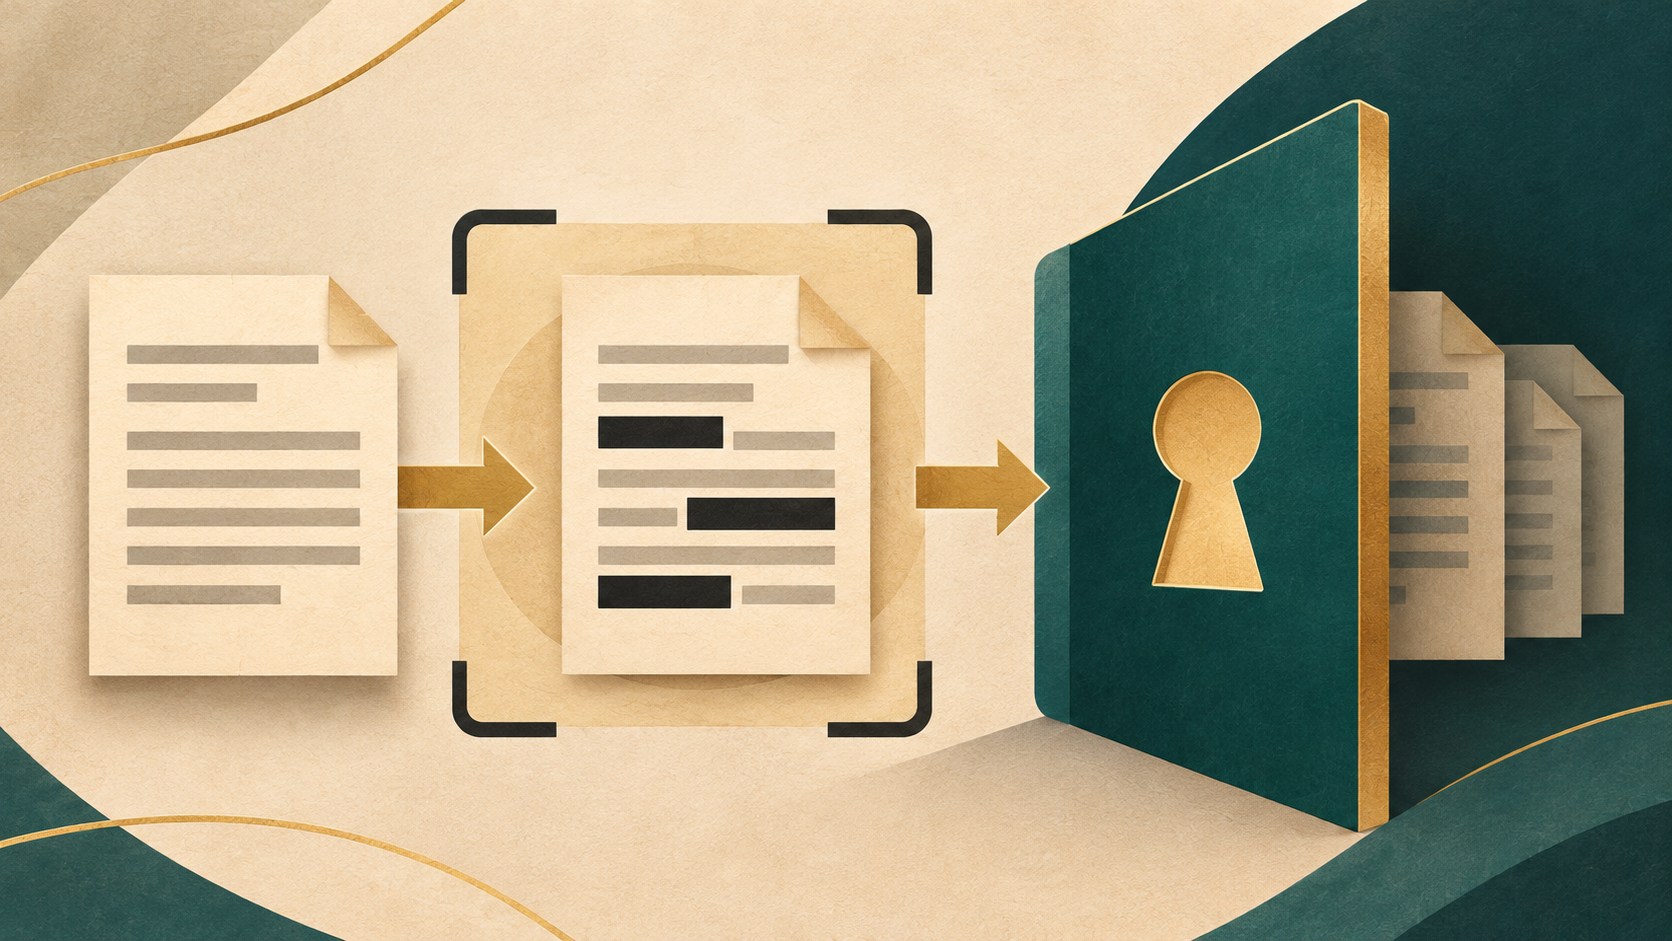
Redaction Is Not Authorization: Set the Boundary Before RAG Ingestion
Redaction can reduce sensitive content in a document, but it does not decide who may retrieve it. Use this practical boundary checklist before indexing enterprise material.
Synthetic Loan Documents: Keep Cross-Document Data Consistent
Build a fictional loan file with consistent borrower, property and loan values, then introduce controlled mismatches to test reconciliation and review.
From PDF to Reliable JSON: Define the Extraction Contract Before the API
Define field meaning, missing-value behavior, source evidence and acceptance rules before connecting document extraction to a downstream application.
How to Test OCR Accuracy on Scanned Documents: A Field-Level Evaluation Guide
Measure OCR and document-extraction quality with known answers, field-level scoring, realistic scan conditions, and a repeatable regression scorecard.

How Regulated Industries Can Accelerate AI Without Compromising Compliance
A practical approach to preparing sensitive documents for AI: define the permitted use, choose the right deployment, validate the output, and make approved workflows repeatable.

Synthetic vs. Sanitized — Choosing the Right Data Strategy for Your AI Team
Choose reviewed real documents, synthetic scenarios, or a combination based on the task, permitted use, and evidence your team needs—not a blanket preference for one data source.

The Hidden Cost of Weak Test Data
Clean samples can hide costly failures in document AI. Build test sets with known answers, realistic input conditions, and explicit checks for the errors that matter to your workflow.

Why AI Teams Don't Have a Data Problem — They Have an Access Problem
When useful enterprise documents cannot reach an approved AI workflow, the answer starts with purpose, permissions, and a usable derivative—not unrestricted access to production records.