Field extraction evals
Check invoice numbers, dates, line items, totals and supplier details. Define acceptable date, currency and whitespace normalization before comparing results.
DOCUMENT AI & EXTRACTION
From purchase order to statement. Every field matters.
Testing OCR on clean PDFs alone doesn’t reflect production conditions. This free pack pairs five documents from one fictional trading relationship with blurred, skewed, coffee-stained, photocopied and cropped versions, so you can see where extraction breaks.
ZIP · 2.0 MB · Free download · No sign-up
 PDF SAMPLE
KNOW WHAT YOU’RE DOWNLOADING
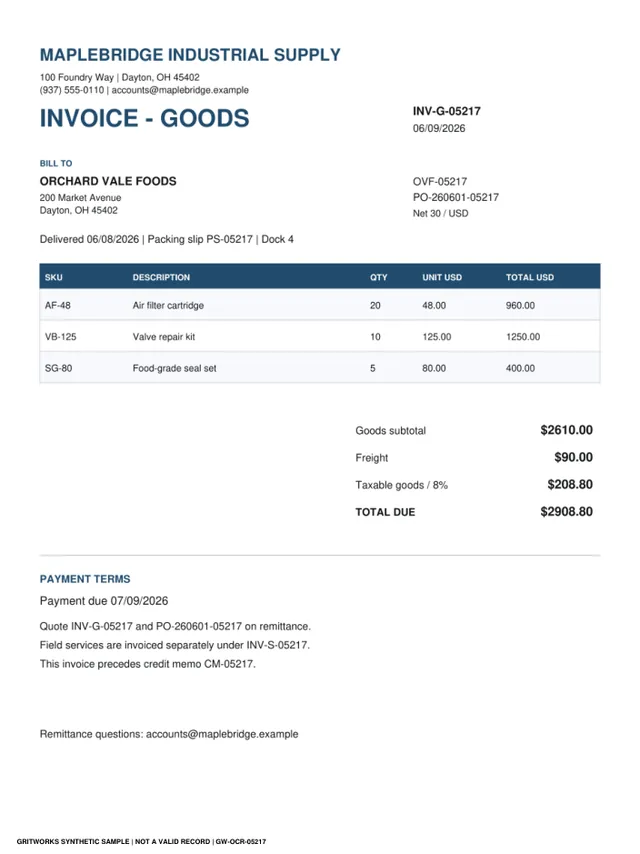
Test invoices, a purchase order, credit memo and account statement from one connected fictional trading relationship. Start with a readable example, then compare its degraded version.
| Document type | Readable example | Challenging version |
|---|---|---|
| 01Purchase order | Clean PDF1 page | Photocopy1 page |
| 02Goods invoice | Clean PDF1 page | Strong blur1 page |
| 03Services invoice | Clean PDF1 page | Coffee stain1 page |
| 04Credit memo | Clean PDF1 page | Skew1 page |
| 05Account statement | Clean PDF1 page | Cropped edges1 page |
10 PDFs plus structured JSON and bounding-box reference files. A file may contain more than one page.
Download the complete packFROM DOWNLOAD TO WORKFLOW
Use a consistent process. Define your expected outputs, run the files and inspect the cases your workflow gets wrong.
Check invoice numbers, dates, line items, totals and supplier details. Define acceptable date, currency and whitespace normalization before comparing results.
Exercise PDF ingestion, extraction responses and downstream validation without connecting a customer document store.
Run the same document pairs after a model, prompt or pipeline change. Separate clean-document errors from errors introduced by image degradation.
FROM SAMPLE TO WORKFLOW
Start with the PDFs. When you need more volume, your own layouts or a safe way to use real records, bring in GritRender and GritRedact.
Need thousands of synthetic documents with different layouts and edge cases? We can generate them.
Explore GritRender →PROTECT · GritRedactWorking with real customer documents? We can help remove sensitive information before testing.
Explore GritRedact →EXTRACT · GritTransformExplore extraction from PDFs and images into structured JSON for your applications.
Explore GritTransform →Implementation and operational support are available around GritWorks products.
CUSTOM DATASETS · MANAGED SERVICE
Need custom datasets but don’t want to build and maintain the generation process internally? Let’s discuss your requirements.
THE NEXT STEP · FREE FOR QUALIFIED TEAMS
Try the sample pack first. When you need more, fill in the booking form and join a call. We’ll review your use case and share the full dataset with qualified teams.
BEFORE YOU START
A ZIP with 10 PDFs: five clean documents and five challenging versions, plus structured JSON and bounding-box JSON for selected populated fields. Some PDFs contain more than one page.
Choose “Download 10 PDFs”. The ZIP downloads directly: no form, call or platform account is required for the sample.
Yes. Use the PDFs and reference files in your own evaluation, sandbox or testing workflow. The included reference data is not an automated scoring system.
It includes structured JSON and bounding boxes for selected populated fields, not every field on every page. Review the coverage and agree normalization rules before you calculate a score.
Choose your dataset, complete the booking form and join a call. We’ll review your use case and share the full dataset with qualified teams. No purchase is required; availability and fit are confirmed on the call.