The practical answer: Evaluate diagnostics documents as a document-extraction task. Compare the expected test name, value, unit and reference range as separate fields; then check how degradation affects the result and the need for review. This does not measure clinical or diagnostic accuracy.
Separate document types first
A lab report, a requisition and a specimen-discrepancy form serve different purposes. Avoid forcing them into a single expected schema just because they all come from a diagnostics workflow.
Define a document type and the intended output for each sample. For a report, that may be a set of result rows. For a registration form, it may be administrative fields. For a requisition, it may be the requested test and the populated order information.
Preserve the relationships between fields
Tabular reports require more than recognizing isolated numbers. A value must stay attached to the correct test, unit and reference range. A correct number copied into the wrong row is still an extraction error.
Build a small reference table from the readable PDF. Record the row label, value, unit, range and any visible flag separately. Decide how to treat blank fields, symbols, decimal separators and values expressed as text. Do not silently infer information that is absent from the source.
Use the paired documents deliberately
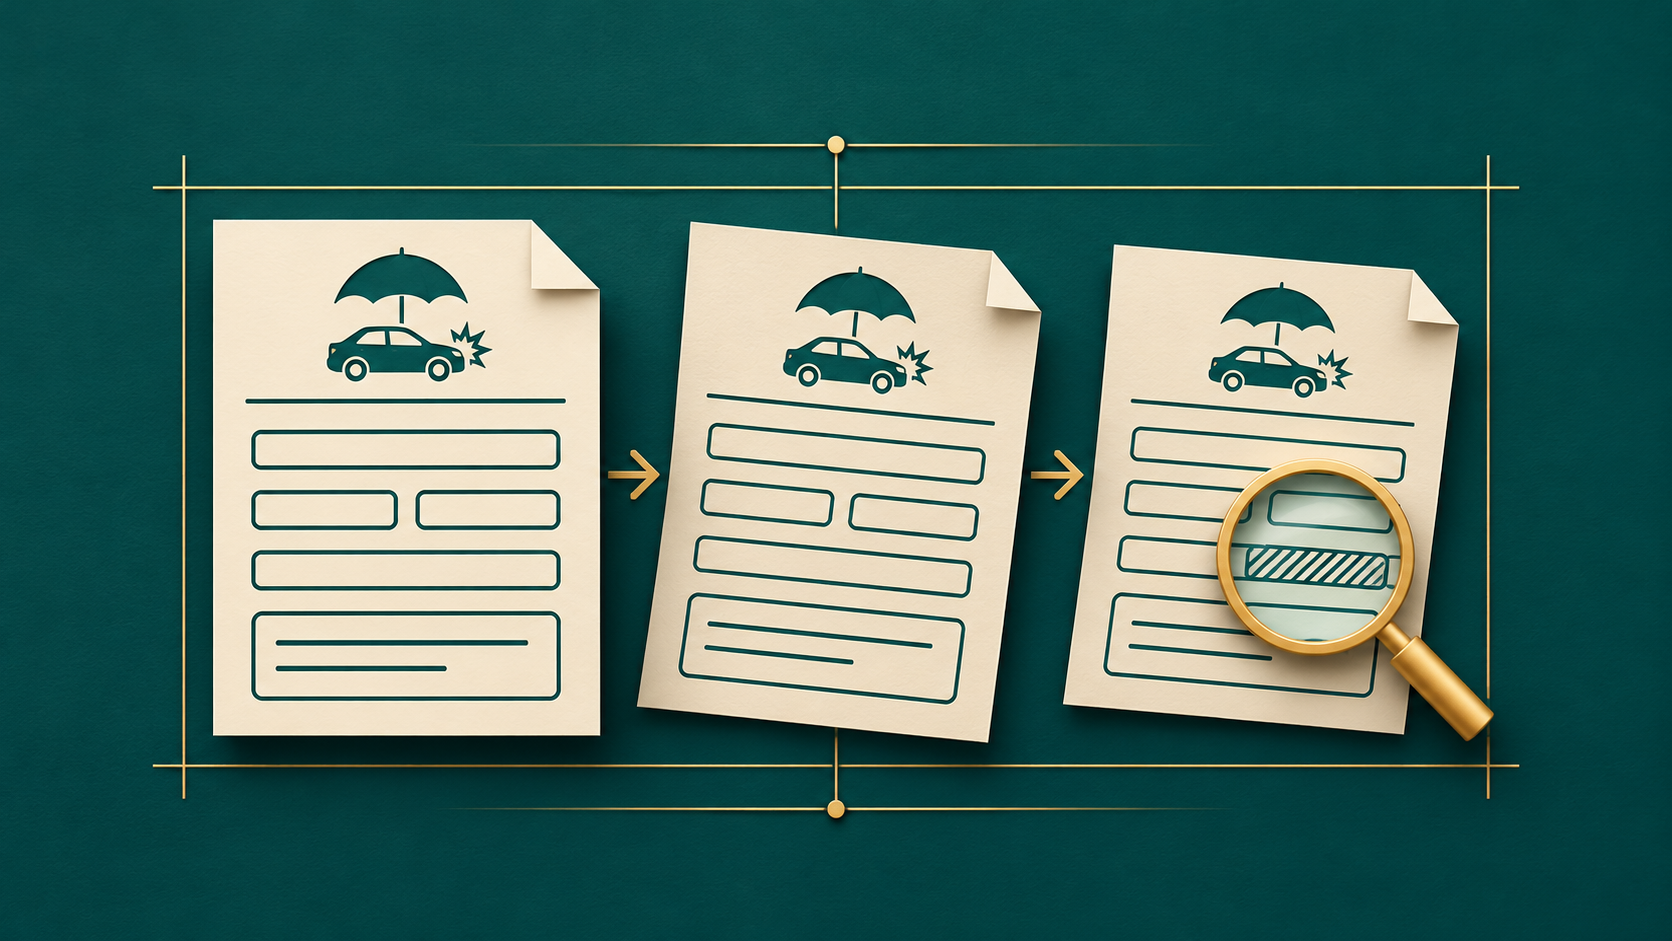
The free diagnostics sample pack follows one fictional patient through five document types: a patient registration, a lab requisition, a physician authorization, a specimen query and a lab report. Each comes as a readable PDF and a degraded counterpart, with a coffee stain, strong blur, photocopy artifacts, cropped edges or low light. Use each readable file to understand the layout before testing its paired challenging version.
Record which failures appear only after degradation. Each PDF in this pack is a single page, and the ten files describe one fictional patient journey, not ten independent clinical records. When you add multi-page reports of your own, check page ordering and continuity as a separate test.
Test uncertainty and review
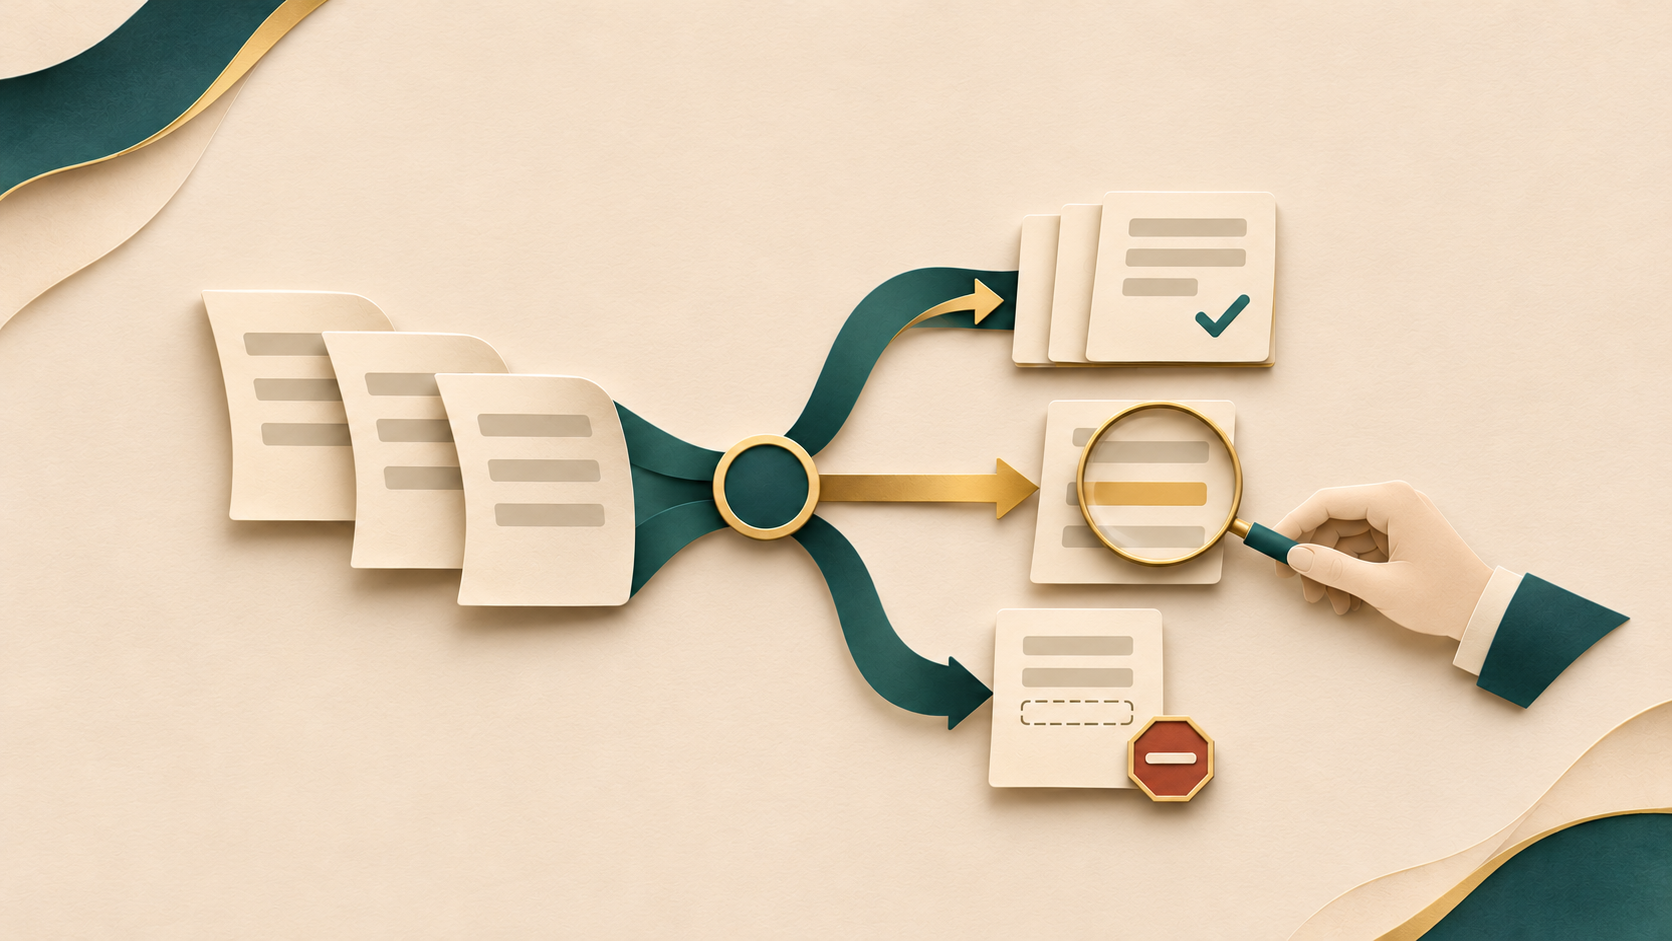
Define the expected behavior when a field cannot be read. That might be an explicit missing value, a review flag or a request for a better scan. Preserve the source page alongside the result so a reviewer can assess what happened.
Measure how often the pipeline produces a wrong value without a review signal. Keep this separate from missing-field counts and ordinary formatting differences. A single overall score can hide a failure that matters to your workflow.
Keep real patient data out of development
Early pipeline work (choosing a parser, mapping fields, tuning prompts, building review screens) rarely needs real patient records. Fictional documents with known values let engineers iterate, attach failing examples to tickets and rerun tests without moving protected health information into development or vendor environments.
When a later stage genuinely needs real documents, decide the permitted use and the recipient first, then prepare a reviewed derivative. GritRedact removes patient identifiers under a configured policy with human review, but automated redaction alone is not a declaration of HIPAA de-identification. The policy, validation and review must match the intended use.
When a fictional set is too small or too uniform, GritRender can create fictional diagnostic reports and requisitions with the layouts, result rows and capture conditions your workflow needs, each with known values.
Report an extraction result, not a clinical claim
This PDF sample is intended for document intake, extraction and sandbox testing. It does not contain clinical outcome labels, radiology images or evidence for diagnostic performance. Successful parsing does not validate an interpretation of the medical content.
For repeatable testing, retain reference values, configuration details and the exact files used. Expand with documents that represent the layouts and conditions relevant to your own workflow before treating a small sample as representative.
Try it with the free diagnostics pack
Download the diagnostics sample pack: ten PDFs, five readable and five degraded, with structured JSON and bounding boxes for selected populated fields. No sign-up.
Explore GritTransform for structured extraction, GritRender for synthetic document generation, and GritRedact when preparing sensitive existing material. Need realistic healthcare documents for AI testing? Talk to our team.