
SYNTHETIC DOCUMENTS BY TYPE
OCR dataset by document type
Pick the document your pipeline has to read. Each page below covers one document type from the free sample packs: what the document contains, how to test OCR and extraction on it, every annotated field with an example value, and a clean and degraded preview. All records are fictional, and the packs arrive by email.
Finance and accounts payable
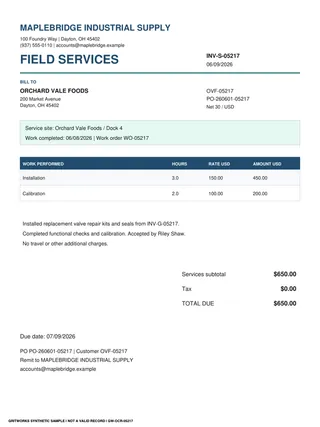
Free synthetic invoice PDFs for invoice OCR and extraction tests: clean and degraded copies, with JSON ground truth for headers, line items and totals.
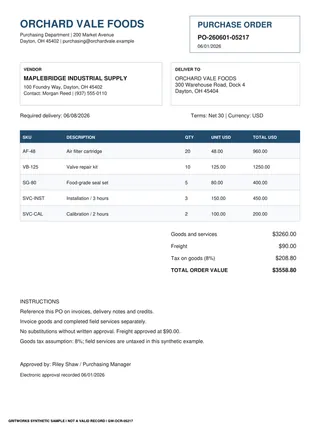
A free sample purchase order PDF, clean and photocopied, with JSON ground truth and bounding boxes for PO OCR and three-way match testing.
Banking and lending
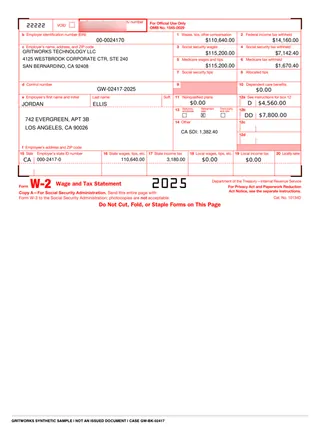
Test income verification workflows with a fictional borrower’s year-end pay stub and W-2, clean and degraded, with JSON ground truth that reconciles.
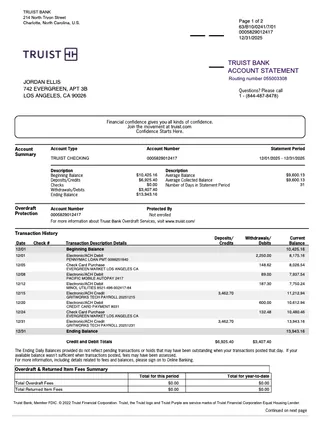
Test bank statement OCR and transaction extraction on a fictional two-page checking statement, clean and photocopied, with row-level JSON ground truth.
Identity and KYC
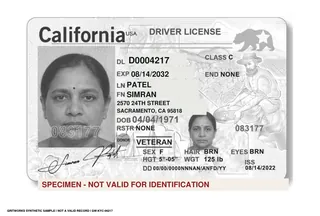
Test document verification workflows with one fictional identity across five marked specimen documents, clean and degraded, with field-level JSON.
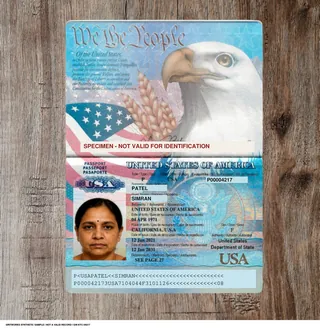
Visibly marked specimen passports for testing MRZ and passport OCR, clean and blurred, with JSON ground truth for both MRZ lines and the printed fields.
Indian languages and handwriting
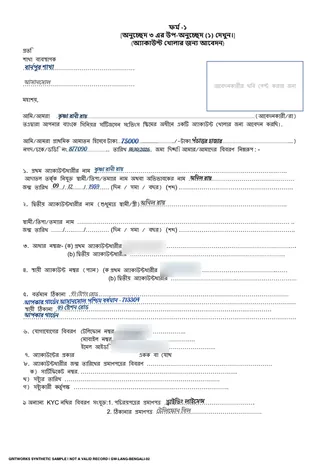
Free forms with handwritten entries in Hindi, Bengali and Marathi, clean and degraded, with JSON ground truth and bounding boxes for each field.
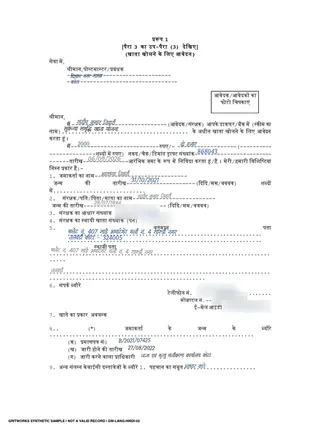
Synthetic Hindi forms for Hindi OCR testing: printed Devanagari with handwritten entries, clean and degraded, with JSON ground truth and bounding boxes.